
Available in: Open/CE, Core, BE, SE, SE+, Ultimate/EE
The module lifecycle stage: Generally available version
The module has requirements for installation
How to explicitly enable or disable the module…
You may explicitly enable or disable the module in one of the following ways:
-
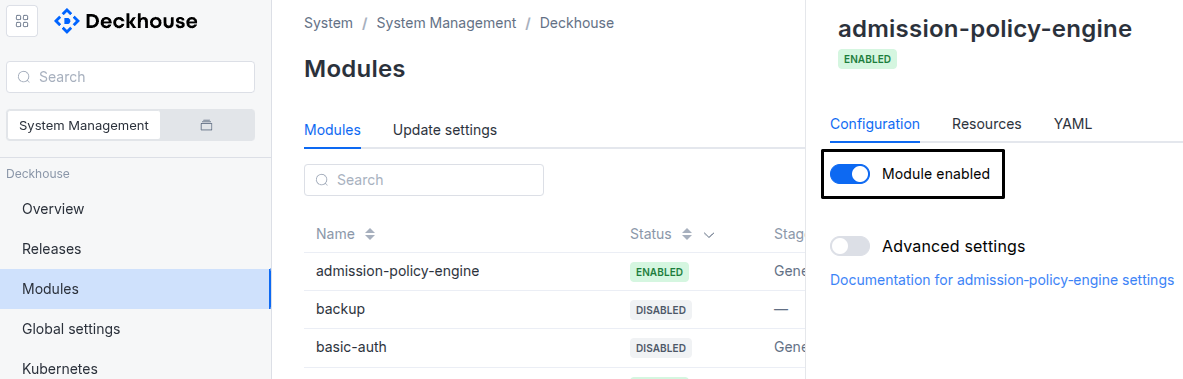
Via Deckhouse web UI. In the “System” → “System Management” → “Deckhouse” → “Modules” section, open the
observabilitymodule and enable (or disable) the “Module enabled” toggle. Save changes.Example:
-
Via Deckhouse CLI (d8).
Use the d8 system module enable command for enabling, or d8 system module disable command for disabling the module (you need Deckhouse CLI (d8), configured to work with the cluster).
Example of enabling the module:
d8 system module enable observability -
Using ModuleConfig
observability.Set
spec.enabledtotrueorfalsein ModuleConfigobservability(create it if necessary).Example of a manifest to enable module
observability:apiVersion: deckhouse.io/v1alpha1 kind: ModuleConfig metadata: name: observability spec: enabled: true
You can configure the module in one of the following ways:
-
Via Deckhouse web UI.
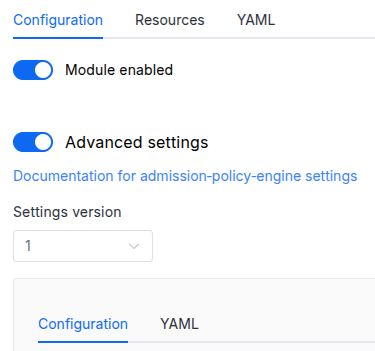
In the “System” → “System Management” → “Deckhouse” → “Modules” section, open the
observabilitymodule and enable the “Advanced Settings” toggle. Fill in the required fields in the “Configuration” tab or specify the module settings in YAML format on the “YAML” tab, without the top-levelsettingskey. Save the changes.Example:
You can also edit the ModuleConfig object
observabilityon the “YAML” tab in the module settings window (“System” → “System Management” → “Deckhouse” → “Modules”, open the moduleobservability) by specifying the schema version in thespec.versionparameter and the necessary module parameters in thespec.settingssection. -
Via Deckhouse CLI (d8) (requires Deckhouse CLI (d8) configured to work with the cluster).
Edit the existing ModuleConfig
observability(for more details on configuring Deckhouse Platform, see the documentation) by executing the following command:d8 k edit mc observabilityMake the necessary changes in the
spec.settingssection. If necessary, specify the schema version in thespec.versionparameter. Save the changes.You can also create a manifest file for ModuleConfig
observabilityusing the example below. Fill in thespec.settingssection with the required module parameters. If necessary, specify the schema version in thespec.versionparameter.Apply the manifest using the following command (indicate the manifest file name):
d8 k apply -f <FILENAME>Example of a manifest for ModuleConfig
observability:apiVersion: deckhouse.io/v1alpha1 kind: ModuleConfig metadata: name: observability spec: version: 2 enabled: true settings: # Module parameters from the "Parameters" section below.
Requirements
To the Deckhouse Platform version: 1.74 and above.
To the versions of other modules:
-
console: 1.41.1 and above. -
operator-prometheus: any version. -
prometheus: any version.
Conversions
The module is configured using the ModuleConfig resource, the schema of which contains a version number. When you apply an old version of the ModuleConfig schema in a cluster, automatic transformations are performed. To manually update the ModuleConfig schema version, the following steps must be completed sequentially for each version:
-
Updates from version 1 to 2:
Delete the
.dop.nodeAffinityfield: the agent collects node metrics instead ofnode-exporterand runs on every node of the cluster, restricting the set of nodes is no longer supported.
Parameters
Schema version: 2
-
-
objectsettings.alertDiagnostics
Experimental. Settings of the diagnostics of firing alerts.
When enabled, the controller
alert-diagnostics-controllerfinds the Kubernetes object of every firing alert, collects facts about it, evaluates the findings of diagnostic playbooks and writes the result into anObservabilityDiagnosticReport(alerts of a namespace) or aClusterObservabilityDiagnosticReport(cluster alerts). The built-in playbooks of the module are installed together with the controller.Default:
{}-
booleansettings.alertDiagnostics.enabled
Experimental. Whether to enable the diagnostics of firing alerts.
When the parameter is turned off, the module deletes all diagnostic reports; playbooks created by users stay.
Default:
false -
objectsettings.alertDiagnostics.linkedTargetsObjects a report follows from the object of the alert: the backend of an Ingress and the dependencies the logs of the containers connect to.
Default:
{}-
integersettings.alertDiagnostics.linkedTargets.maxDepth
Maximum number of objects in a row a report follows from the object of the alert.
0turns the traversal off.A playbook can only lower it with
execution.maxLinkedDepth. A report follows at most 20 objects in total.Default:
5Allowed values:
0 <= X <= 5
-
-
objectsettings.alertDiagnostics.logsLimits of container logs in reports.
Default:
{}-
integersettings.alertDiagnostics.logs.maxBytesPerCheckMaximum number of bytes of one log stream stored in a report.
Default:
32768Allowed values:
1024 <= X <= 262144
-
-
objectsettings.alertDiagnostics.nodeAgent
Settings of the node agent
alert-diagnostics-node-agent.The agent runs on every node and, on request of the controller only, reads on the node: the journal and the state of the systemd units (
kubelet,containerd,containerd-deckhouse,bashible,cloud-init) and the kernel log; the disk usage of its file systems and of the writable layers of containers; the listening sockets of pods; the counters of connection tracking; the clock; the audit log of kube-apiserver on control-plane nodes. It mounts the root file system of the node read-only, listens on port 4294/TCP of the node address with mutual TLS and changes nothing on the node.Default:
{}-
booleansettings.alertDiagnostics.nodeAgent.enabled
Whether to run the node agent while the diagnostics is enabled.
When disabled, the agent is not deployed, and the checks of the reports that read a node end with the outcome
Skipped.Default:
true
-
-
objectsettings.alertDiagnostics.podExecSettings of the
PodExecchecks that run fixed commands of playbooks in containers.Default:
{}-
booleansettings.alertDiagnostics.podExec.enabled
Whether to allow
PodExecchecks.When enabled, the controller gets the right to run commands in the containers of every namespace of the cluster (
pods/exec), including the namespaces of the platform; it runs only the fixed commands of the playbooks. Turn it off where this right is not acceptable.When disabled, the controller has no right to run commands in containers (
pods/exec) and the checks end with the outcomeSkipped.Default:
true
-
-
objectsettings.alertDiagnostics.rerunSettings of manual runs of the diagnostics.
Default:
{}-
stringsettings.alertDiagnostics.rerun.minIntervalMinimum interval between the start of a run and the next manual run of the same alert.
Default:
5mPattern:
^([0-9]+(ns|us|ms|s|m|h))+$Example:
minInterval: 5m
-
-
objectsettings.alertDiagnostics.retentionRetention of diagnostic reports.
Default:
{}-
stringsettings.alertDiagnostics.retention.lostTTL
How long the report of an alert whose object disappeared without resolving stays available before it is deleted.
Hours and minutes, at least one minute:
15m,24h,1h30m.Default:
15mPattern:
^([1-9][0-9]*h([0-9]+m)?|([0-9]+h)?[1-9][0-9]*m)$Examples:
lostTTL: 15mlostTTL: 24h -
integersettings.alertDiagnostics.retention.maxReports
Maximum number of reports in the cluster,
ObservabilityDiagnosticReportandClusterObservabilityDiagnosticReportcounted together.When the limit is reached, creating a report first deletes a report of a finished alert: failed reports without facts first, then reports of alerts that disappeared, then reports of resolved alerts, the oldest first. Reports of firing alerts are never deleted. When every report belongs to a firing alert, the automatic creation waits, and a report created by a user is accepted while the total stays below the limit plus 50.
Reports without diagnostics (the reason
NoDiagnostics: no playbook matches the alert and its labels name no object) are not counted and are not deleted to make room; they are deleted byresolvedTTLandlostTTL.Default:
300Allowed values:
10 <= X <= 3000 -
stringsettings.alertDiagnostics.retention.resolvedTTL
How long the report of a resolved alert stays available before it is deleted.
Hours and minutes, at least one minute:
15m,24h,1h30m.Default:
15mPattern:
^([1-9][0-9]*h([0-9]+m)?|([0-9]+h)?[1-9][0-9]*m)$Examples:
resolvedTTL: 15mresolvedTTL: 24h
-
-
-
objectsettings.deadMansSwitchSettings for the DeadMansSwitch alerting.
Default:
{}-
booleansettings.deadMansSwitch.enabled
Whether to enable DeadMansSwitch alert handling.
When enabled (default), a DeadMansSwitch heartbeat alert is expected from Prometheus and a PrometheusUnavailable alert is generated if the heartbeat is missing. When disabled, neither DeadMansSwitch nor PrometheusUnavailable alerts are created.
Default:
true
-
-
objectsettings.dopSettings for integration with DOP (Deckhouse Observability Platform).
Default:
{}-
array of objectssettings.dop.destinationsList of DOP destinations for metrics delivery. At least one destination is required.
Example:
destinations: - host: dop.flant.com token: your-api-token-here-
stringsettings.dop.destinations.hostDOP platform host address (must be a valid FQDN, e.g., dop.flant.com).
Length:
1..253Pattern:
^[a-zA-Z0-9]([a-zA-Z0-9-]{0,61}[a-zA-Z0-9])?(\.[a-zA-Z0-9]([a-zA-Z0-9-]{0,61}[a-zA-Z0-9])?)*$ -
stringsettings.dop.destinations.tokenAPI token for the DOP platform (UUID format).
Pattern:
^[a-fA-F0-9]{8}-[a-fA-F0-9]{4}-[a-fA-F0-9]{4}-[a-fA-F0-9]{4}-[a-fA-F0-9]{12}$
-
-
booleansettings.dop.hostMetricsWhether to enable nodes metrics collection with okagent.
Default:
true
-
-
objectsettings.externalMetricsAccessSettings for external access to metrics.
Default:
{}-
booleansettings.externalMetricsAccess.enabled
Whether to enable metrics external read access.
If enabled, the
observabilitymodule will expose the metrics via ingress for reading. Metrics can be read using the Prometheus-compatible API. Providing a valid ServiceAccount token via theAuthorization: Bearerheader is mandatory. For details, refer to “External access to metrics”.Default:
false -
array of stringssettings.externalMetricsAccess.whitelistSourceRangesAn array if CIDRs that are allowed to read metrics. If not specified, no restrictions are applied.
Default:
[]Example:
whitelistSourceRanges: - 1.1.1.1/32-
stringsettings.externalMetricsAccess.whitelistSourceRanges.Element of the array
Pattern:
^(((25[0-5]|2[0-4][0-9]|1[0-9]{2}|[1-9]?[0-9])\.){3}(25[0-5]|2[0-4][0-9]|1[0-9]{2}|[1-9]?[0-9])(/([0-9]|[12][0-9]|3[0-2]))?|([0-9A-Fa-f]{0,4}:){2,7}[0-9A-Fa-f]{0,4}(/([0-9]|[1-9][0-9]|1[01][0-9]|12[0-8]))?)$
-
-
-
objectsettings.grafanaGrafana related settings.
Default:
{}-
array of stringssettings.grafana.customPlugins
A list of custom Grafana plugins. Contains plugin names from the official repository.
Here is how you can add custom plugins (in this case, clickhouse-datasource and flowcharting-panel plugins are used):
grafana:
  customPlugins:
  - agenty-flowcharting-panel
  - vertamedia-clickhouse-datasource
You can also install plugins from other sources by passing a link to the plugin zip archive in the format
<url to plugin zip>;<plugin name>:grafana: customPlugins: - http://10.241.32.16:3000/netsage-bumpchart-panel-1.1.1.zip;netsage-bumpchart-panelExample:
customPlugins:
- agenty-flowcharting-panel
- vertamedia-clickhouse-datasource
-
-
booleansettings.highAvailability
Manually enable the high availability mode.
By default, the mode is taken from the global
highAvailabilityparameter; if it is not set, the mode is enabled when the cluster control plane is highly available.alert-kube-apiandobservability-webhookalways run in two replicas regardless of this parameter.Examples:
highAvailability: truehighAvailability: false -
objectsettings.https
What certificate type to use with observability module.
This parameter completely overrides the
global.modules.httpssettings.Examples:
customCertificate: secretName: foobar mode: CustomCertificatecertManager: clusterIssuerName: letsencrypt mode: CertManager-
objectsettings.https.certManager
-
stringsettings.https.certManager.clusterIssuerName
What ClusterIssuer to use for the observability module.
Currently,
letsencrypt,letsencrypt-staging,selfsignedare available. Also, you can define your own.Default:
letsencrypt
-
-
objectsettings.https.customCertificate
Default:
{}-
stringsettings.https.customCertificate.secretName
The name of the secret in the
d8-systemnamespace to use with the observability module.This secret must have the kubernetes.io/tls format.
Default:
false
-
-
stringsettings.https.mode
The HTTPS usage mode:
Disabled— the observability module will work over HTTP only;CertManager— the observability module will use HTTPS and get a certificate from the clusterissuer defined in thecertManager.clusterIssuerNameparameter.CustomCertificate— the observability module will use HTTPS using the certificate from thed8-systemnamespace.OnlyInURI— the observability module will work over HTTP (thinking that there is an external HTTPS load balancer in front that terminates HTTPS traffic). All the links in theuser-authnwill be generated using the HTTPS scheme. Load balancer should provide a redirect from HTTP to HTTPS.
Default:
DisabledAllowed values:
Disabled,CertManager,CustomCertificate,OnlyInURI
-
-
stringsettings.ingressClass
The ingress class to use for all ingress resources created by the observability module.
This parameter completely overrides the
global.modules.ingressClasssettings. If not specified, the global ingress class configuration will be used.The value must be a valid Kubernetes resource name (lowercase alphanumeric characters or hyphens, must start and end with alphanumeric character).
Pattern:
^[a-z0-9]([-a-z0-9]*[a-z0-9])?$Examples:
ingressClass: nginxingressClass: nginx-external -
objectsettings.lightweightLogsSettings for lightweight logs collection directly from kubelet.
Default:
{ "enabled": true }-
booleansettings.lightweightLogs.enabledWhether to enable lightweight logs collection from kubelet.
Default:
true
-
-
objectsettings.lokiSettings for the built-in Loki log storage.
Default:
{}-
booleansettings.loki.allowDeleteLogsAllow logs deletion using /loki/api/v1/delete endpoints.
Default:
false -
objectsettings.loki.distributedSettings for the
Distributedmode (Loki Simple Scalable). Requiresstorage.type: S3.Default:
{}-
objectsettings.loki.distributed.backendSettings for the
backendtarget, which runs the compactor, index gateway, query scheduler and ruler.Default:
{}-
integersettings.loki.distributed.backend.replicasNumber of
backendreplicas.Default:
2Allowed values:
2 <= X -
settings.loki.distributed.backend.resourcesManagementSettings for CPU and memory requests and limits of the
backendpods.Default:
{}-
stringsettings.loki.distributed.backend.resourcesManagement.mode
Resource management mode:
Staticis a classic one. In it, you specify requests/limits.VPAmode uses VPA.
Default:
VPAAllowed values:
VPA,Static -
objectsettings.loki.distributed.backend.resourcesManagement.static
-
objectsettings.loki.distributed.backend.resourcesManagement.static.limits
-
settings.loki.distributed.backend.resourcesManagement.static.limits.cpu
-
settings.loki.distributed.backend.resourcesManagement.static.limits.memory
-
-
objectsettings.loki.distributed.backend.resourcesManagement.static.requests
-
settings.loki.distributed.backend.resourcesManagement.static.requests.cpu
-
settings.loki.distributed.backend.resourcesManagement.static.requests.memory
-
-
-
objectsettings.loki.distributed.backend.resourcesManagement.vpaResource management options for the
VPAmode.Default:
{}-
objectsettings.loki.distributed.backend.resourcesManagement.vpa.cpu
Default:
{}-
numbersettings.loki.distributed.backend.resourcesManagement.vpa.cpu.limitRatio
-
settings.loki.distributed.backend.resourcesManagement.vpa.cpu.max
Default:
2 -
settings.loki.distributed.backend.resourcesManagement.vpa.cpu.min
Default:
50m
-
-
objectsettings.loki.distributed.backend.resourcesManagement.vpa.memory
Default:
{}-
numbersettings.loki.distributed.backend.resourcesManagement.vpa.memory.limitRatio
-
settings.loki.distributed.backend.resourcesManagement.vpa.memory.max
Default:
2Gi -
settings.loki.distributed.backend.resourcesManagement.vpa.memory.min
Default:
256Mi
-
-
stringsettings.loki.distributed.backend.resourcesManagement.vpa.mode
Default:
InPlaceOrRecreateAllowed values:
Initial,InPlaceOrRecreate,Auto
-
-
-
-
objectsettings.loki.distributed.readSettings for the
readtarget, which serves queries.Default:
{}-
integersettings.loki.distributed.read.replicasNumber of
readreplicas.Default:
3Allowed values:
1 <= X -
settings.loki.distributed.read.resourcesManagementSettings for CPU and memory requests and limits of the
readpods.Default:
{}-
stringsettings.loki.distributed.read.resourcesManagement.mode
Resource management mode:
Staticis a classic one. In it, you specify requests/limits.VPAmode uses VPA.
Default:
VPAAllowed values:
VPA,Static -
objectsettings.loki.distributed.read.resourcesManagement.static
-
objectsettings.loki.distributed.read.resourcesManagement.static.limits
-
settings.loki.distributed.read.resourcesManagement.static.limits.cpu
-
settings.loki.distributed.read.resourcesManagement.static.limits.memory
-
-
objectsettings.loki.distributed.read.resourcesManagement.static.requests
-
settings.loki.distributed.read.resourcesManagement.static.requests.cpu
-
settings.loki.distributed.read.resourcesManagement.static.requests.memory
-
-
-
objectsettings.loki.distributed.read.resourcesManagement.vpaResource management options for the
VPAmode.Default:
{}-
objectsettings.loki.distributed.read.resourcesManagement.vpa.cpu
Default:
{}-
numbersettings.loki.distributed.read.resourcesManagement.vpa.cpu.limitRatio
-
settings.loki.distributed.read.resourcesManagement.vpa.cpu.max
Default:
2 -
settings.loki.distributed.read.resourcesManagement.vpa.cpu.min
Default:
50m
-
-
objectsettings.loki.distributed.read.resourcesManagement.vpa.memory
Default:
{}-
numbersettings.loki.distributed.read.resourcesManagement.vpa.memory.limitRatio
-
settings.loki.distributed.read.resourcesManagement.vpa.memory.max
Default:
2Gi -
settings.loki.distributed.read.resourcesManagement.vpa.memory.min
Default:
256Mi
-
-
stringsettings.loki.distributed.read.resourcesManagement.vpa.mode
Default:
InPlaceOrRecreateAllowed values:
Initial,InPlaceOrRecreate,Auto
-
-
-
-
objectsettings.loki.distributed.writeSettings for the
writetarget, which accepts pushes and flushes chunks to the store.Default:
{}-
integersettings.loki.distributed.write.replicas
Number of
writereplicas.Cannot be lower than 3: the ring is configured with a replication factor of 3.
Default:
3Allowed values:
3 <= X -
settings.loki.distributed.write.resourcesManagementSettings for CPU and memory requests and limits of the
writepods.Default:
{}-
stringsettings.loki.distributed.write.resourcesManagement.mode
Resource management mode:
Staticis a classic one. In it, you specify requests/limits.VPAmode uses VPA.
Default:
VPAAllowed values:
VPA,Static -
objectsettings.loki.distributed.write.resourcesManagement.static
-
objectsettings.loki.distributed.write.resourcesManagement.static.limits
-
settings.loki.distributed.write.resourcesManagement.static.limits.cpu
-
settings.loki.distributed.write.resourcesManagement.static.limits.memory
-
-
objectsettings.loki.distributed.write.resourcesManagement.static.requests
-
settings.loki.distributed.write.resourcesManagement.static.requests.cpu
-
settings.loki.distributed.write.resourcesManagement.static.requests.memory
-
-
-
objectsettings.loki.distributed.write.resourcesManagement.vpaResource management options for the
VPAmode.Default:
{}-
objectsettings.loki.distributed.write.resourcesManagement.vpa.cpu
Default:
{}-
numbersettings.loki.distributed.write.resourcesManagement.vpa.cpu.limitRatio
-
settings.loki.distributed.write.resourcesManagement.vpa.cpu.max
Default:
2 -
settings.loki.distributed.write.resourcesManagement.vpa.cpu.min
Default:
50m
-
-
objectsettings.loki.distributed.write.resourcesManagement.vpa.memory
Default:
{}-
numbersettings.loki.distributed.write.resourcesManagement.vpa.memory.limitRatio
-
settings.loki.distributed.write.resourcesManagement.vpa.memory.max
Default:
2Gi -
settings.loki.distributed.write.resourcesManagement.vpa.memory.min
Default:
256Mi
-
-
stringsettings.loki.distributed.write.resourcesManagement.vpa.mode
Default:
InPlaceOrRecreateAllowed values:
Initial,InPlaceOrRecreate,Auto
-
-
-
-
-
booleansettings.loki.enabledWhether to enable the built-in Loki log storage.
Default:
false -
objectsettings.loki.lokiConfig
Loki configuration options available for tuning.
See Loki documentation for more information.
Caution! Incorrect settings may lead to the malfunction of Loki.
Default:
{}-
integersettings.loki.lokiConfig.grpcServerMaxConcurrentStreamsLimit on the number of concurrent streams for gRPC calls.
Default:
100 -
integersettings.loki.lokiConfig.grpcServerMaxRecvMsgSizeLimit on the size of a gRPC message this server can receive in bytes.
Default:
104857600 -
integersettings.loki.lokiConfig.grpcServerMaxSendMsgSizeLimit on the size of a gRPC message this server can send in bytes.
Default:
4194304 -
numbersettings.loki.lokiConfig.ingestionBurstSizeMBOverall ingestion burst size in megabytes. E.g., maximum push request size.
Default:
6 -
numbersettings.loki.lokiConfig.ingestionRateMBOverall ingestion rate limit in megabytes per second.
Default:
4 -
integersettings.loki.lokiConfig.maxChunksPerQueryThe maximum number of chunks that can be fetched per query.
Default:
2000000 -
integersettings.loki.lokiConfig.maxEntriesLimitPerQueryThe maximum number of entries returned for the query.
Default:
5000 -
integersettings.loki.lokiConfig.maxLabelNamesPerSeriesThe maximum number of unique label names per series (log stream).
Default:
32 -
integersettings.loki.lokiConfig.maxStreamsPerUser
The maximum total number of streams for the Loki instance.
Each stream has unique labels. The number of streams is the number of unique label sets.
0 means unlimited.
Default:
0 -
settings.loki.lokiConfig.perStreamRateLimitMaximum byte rate per second per stream. Can be either a number or a string with a unit (KB, MB, GB).
Default:
3MB -
settings.loki.lokiConfig.perStreamRateLimitBurstMaximum burst size per stream. Can be either a number or a string with a unit (KB, MB, GB).
Default:
15MB
-
-
stringsettings.loki.mode
Deployment mode.
Single— a single monolithic Loki instance. Configured via the single parameters.Distributed— Loki in the Simple Scalable topology, with separatewrite,readandbackendtargets. Requiresstorage.type: S3and is configured via the distributed parameters.
Warning. Switching the mode does not migrate the data: the new instance starts empty. A disk left over from the previous mode is not deleted automatically.
Default:
SingleAllowed values:
Single,Distributed -
objectsettings.loki.nodeSelector
The same as the Pods’
spec.nodeSelectorparameter in Kubernetes. Applies to every Loki Pod:lokiinSinglemode,write,readandbackendinDistributedmode.If the parameter is omitted or empty,
nodeSelectorwill be determined automatically.Example:
node-role.deckhouse.io/loki: '' -
integersettings.loki.retentionPeriodHours
The desired minimum log retention period in hours.
With
storage.type: Diskthis parameter does not cap the retention depth: old data is only deleted once the disk fills up. If Loki deletes data that has not yet reached the specified retention period, you will receive aLokiInsufficientDiskForRetentionalert. In this case, you should either increase the disk size or decrease the value of this parameter.With
storage.type: S3(in either mode) the compactor enforces this period directly, and data older than it is deleted regardless of how much space is left.Default:
168 -
objectsettings.loki.singleSettings for the
Singlemode.Default:
{}-
settings.loki.single.resourcesManagementSettings for CPU and memory requests and limits of the Loki pod.
Default:
{}-
stringsettings.loki.single.resourcesManagement.mode
Resource management mode:
Staticis a classic one. In it, you specify requests/limits.VPAmode uses VPA.
Default:
VPAAllowed values:
VPA,Static -
objectsettings.loki.single.resourcesManagement.static
-
objectsettings.loki.single.resourcesManagement.static.limits
-
settings.loki.single.resourcesManagement.static.limits.cpu
-
settings.loki.single.resourcesManagement.static.limits.memory
-
-
objectsettings.loki.single.resourcesManagement.static.requests
-
settings.loki.single.resourcesManagement.static.requests.cpu
-
settings.loki.single.resourcesManagement.static.requests.memory
-
-
-
objectsettings.loki.single.resourcesManagement.vpaResource management options for the
VPAmode.Default:
{}-
objectsettings.loki.single.resourcesManagement.vpa.cpu
Default:
{}-
numbersettings.loki.single.resourcesManagement.vpa.cpu.limitRatio
-
settings.loki.single.resourcesManagement.vpa.cpu.max
Default:
2 -
settings.loki.single.resourcesManagement.vpa.cpu.min
Default:
50m
-
-
objectsettings.loki.single.resourcesManagement.vpa.memory
Default:
{}-
numbersettings.loki.single.resourcesManagement.vpa.memory.limitRatio
-
settings.loki.single.resourcesManagement.vpa.memory.max
Default:
2Gi -
settings.loki.single.resourcesManagement.vpa.memory.min
Default:
256Mi
-
-
stringsettings.loki.single.resourcesManagement.vpa.mode
Default:
InPlaceOrRecreateAllowed values:
Initial,InPlaceOrRecreate,Auto
-
-
-
-
objectsettings.loki.storageWhere Loki keeps its data. The storage is a property of the installation and does not depend on the mode.
Default:
{}-
objectsettings.loki.storage.disk
The PersistentVolume of every stateful Loki pod:
lokiinSinglemode,writeandbackendinDistributedmode. The disk is always there;storage.typedecides what is kept on it.Disk— chunks, the index and the write-ahead log. Size it for the period set byretentionPeriodHours: when the disk fills up, the oldest logs are evicted.S3— only the write-ahead log, the index cache and the compactor scratch space. A small disk is enough, the default size is fine. Retention is enforced by age through the compactor.
Default:
{}-
integersettings.loki.storage.disk.sizeGigabytes
Disk size in gigabytes.
With
storage.type: Diskyou should manually specify the size required to store logs for the period defined by theretentionPeriodHoursparameter.Note. While a disk is being adopted from the standalone
lokimodule, the size of the existing volume is used and this parameter is ignored. Resize the PersistentVolumeClaim afterwards if a larger disk is needed.Default:
2 -
settings.loki.storage.disk.storageClass
The name of StorageClass that will be used for the disk.
If omitted, the StorageClass of the existing Loki PersistentVolumeClaim is used. If there is no claim yet, the StorageClass will be used according to the global storageClass parameter setting.
false— an emptyDir is used instead of a PersistentVolume, and the data on it does not survive a pod restart.Warning. Specifying a value different from the one currently used (in the existing claim) will result in disk re-provisioning and all data will be deleted.
Examples:
storageClass: falsestorageClass: default
-
objectsettings.loki.storage.s3Parameters used when
storage.typeisS3.Default:
{}-
stringsettings.loki.storage.s3.accessKeyIDS3 access key ID.
-
stringsettings.loki.storage.s3.bucketBucket name for Loki chunks and indexes.
-
stringsettings.loki.storage.s3.endpointS3-compatible storage endpoint URL.
-
booleansettings.loki.storage.s3.insecureDisable TLS certificate verification for the S3 endpoint.
Default:
false -
stringsettings.loki.storage.s3.regionAWS region or its equivalent for the S3 API.
-
booleansettings.loki.storage.s3.s3ForcePathStyleForce path-style S3 URLs. Required for MinIO and some other providers.
Default:
false -
stringsettings.loki.storage.s3.secretAccessKeyS3 secret access key.
-
-
stringsettings.loki.storage.type
Where chunks and the index live.
Disk— on the PersistentVolume described by the storage.disk parameters. The only backend with disk-based retention. Available inSinglemode only: theDistributedtargets share the store.S3— in an S3-compatible object storage, configured via the storage.s3 parameters. The disk then holds only the write-ahead log, the index cache and the compactor scratch space.
Default:
DiskAllowed values:
Disk,S3
-
-
booleansettings.loki.storeSystemLogs
Save logs from the
d8-*namespaces to loki.The log-shipper module must be enabled.
Default:
true -
array of objectssettings.loki.tolerations
The same as the Pods’
spec.tolerationsparameter in Kubernetes. Applies to every Loki Pod:lokiinSinglemode,write,readandbackendinDistributedmode.If the parameter is omitted or empty,
tolerationswill be determined automatically.Example:
tolerations: - effect: NoExecute key: dedicated.deckhouse.io operator: Equal value: loki-
stringsettings.loki.tolerations.effect
-
stringsettings.loki.tolerations.key
-
stringsettings.loki.tolerations.operator
-
integersettings.loki.tolerations.tolerationSeconds
-
stringsettings.loki.tolerations.value
-
-
-
objectsettings.opagentSettings for the opagent host metrics collector.
Default:
{}-
array of objectssettings.opagent.pingExternalTargets
A list of additional hosts outside the cluster that the agent pings from every node.
Cluster nodes are pinged without this setting; the list adds external hosts. A host is not checked for format: a name that does not resolve to an IPv4 address is still listed in the metrics, but its packet counters do not grow.
Default:
[]Example:
pingExternalTargets: - host: 8.8.8.8 name: google-dns - host: ya.ru-
stringsettings.opagent.pingExternalTargets.hostIP address or host name to monitor.
Length:
1..253Pattern:
(?s).*\S.* -
stringsettings.opagent.pingExternalTargets.nameMonitoring record name. If not set, the host is used as the name.
Maximum length:
253
-
-
integersettings.opagent.scrapeInterval
Interval (in seconds) at which opagent collects host metrics.
Should typically match the cluster’s Prometheus scrape_interval to avoid mismatched data density in Grafana dashboards backed by the same datasource.
Default:
30Allowed values:
10 <= X
-
-
objectsettings.polkAnnotationsSettings for Polk-specific alert annotations handling.
Default:
{}-
booleansettings.polkAnnotations.enabled
Whether to keep Polk-specific alert annotations (with the
plk_prefix) in incoming alerts.When enabled (default),
plk_*annotations are preserved in alerts for all notification receivers. When disabled, allplk_*annotations are removed from alerts when sending notifications to any receiver.Default:
true
-
-